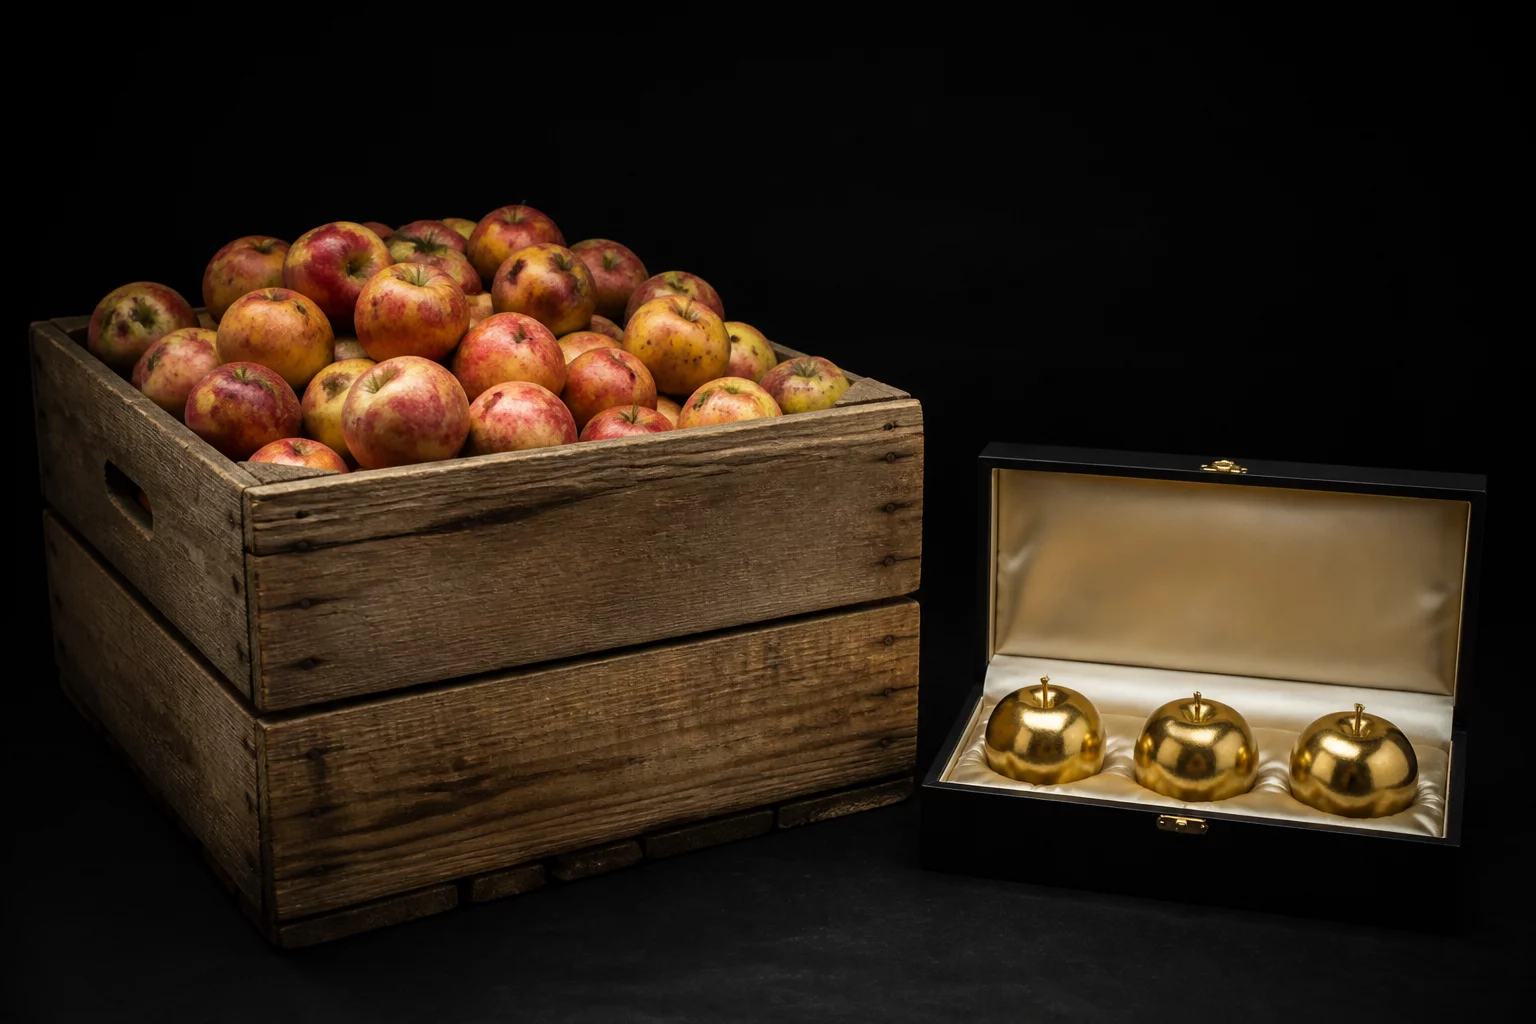
Methodological Distinction
Volume Compounding Error
Research teams often treat an enormous participant registry as proof of rigorous methodology. In reality, observation count merely tightens confidence intervals around whatever value the process captures. When selection mechanisms skew toward vocal subgroups, large numbers do not correct the drift; they lock in systemic errors with false certainty.
Structural Realities
-
01
Precision vs Accuracy:
Narrow intervals around biased means produce false precision.
-
02
Coverage Deficit:
Excluding target segments distorts findings regardless of volume.
-
03
Instrument Noise:
Uncalibrated question wording consistently yields uninterpretable returns.
Audit Your Protocol
Examine sampling frames, non-response dynamics, and calibration before spending resources on expanding panel volume.
Consult Our Specialists
01 Unpacking the Big Data Paradox
Statisticians refer to the illusion of large registries as the big data paradox. When sample recruitment depends on opt-in convenience portals or social media outreach, people who opt in differ substantially from passive populations. Doubling or tripling the respondent pool does not dilute these motivational biases. It merely amplifies statistical significance for artifacts of the sampling scheme.
Consider an organizational audit collecting ten thousand employee reviews through an anonymous intranet link. Workers with extreme dissatisfaction or exceptional enthusiasm fill the queue, while the vast moderate middle ignores the prompt. A simple random sample of four hundred verified employees with enforced follow-up yields far closer estimates to genuine workplace sentiment than tens of thousands of voluntary submissions.
Master Protocol Scoping
Learn how to calculate sample thresholds anchored to realistic effect sizes and risk tolerances.
Explore Method Guide
02 Instrument Quality and Attrition Traps
Questionnaire design and measurement integrity govern data utility far more than record counts. If respondents encounter ambiguous Likert scale prompts or leading stems, every individual answer contains systematic drift. Gathering five thousand responses through a misworded prompt preserves the error at scale, producing smooth distribution curves that reflect confusing wording rather than respondent reality.
A sample of fifty thousand biased records delivers exact certainty about the wrong question. True quality stems from valid instruments, balanced probability frames, and verified response fidelity.
— Review Board Editorial Guidelines, 2026
Participant attrition during longitudinal observation presents an identical danger. When individuals abandon multi-wave trials, those who drop out rarely do so at random. Even if initial enrollments exceed statistical power targets, post-attrition cohorts reflect survival criteria instead of baseline populations, rendering headline headcounts meaningless.
03 Methodological Clarifications
Address standard misalignments when evaluating study integrity versus raw observation counts in research proposals.
No. Expanding participant volume reduces random sampling error and narrows confidence bands. It does not rectify non-response bias, flawed sample frames, or selective reporting. Systematic skew persists regardless of how many records enter the dataset.
A smaller sample is superior whenever available resources can be concentrated on rigorous contact strategies, high response completion rates, validated instrumentation, and thorough data auditing rather than chasing unvetted respondent bulk.
Reviewers should examine sampling frame alignment, non-response adjustment methods, pilot calibration results, and operational attrition before considering raw sample numbers. Methodological validity must always take precedence over scale.
Topics:
Sampling Bias
Measurement Quality
Statistical Power
Data Rigor